

 脚本语言

关于python爬虫程序中途停止的问题
 墨衍会员 · AI 创作全网分发 墨衍智能分发 通过墨衍一键同步至各平台 可同步平台 CSDN微信公众号微博知乎掘金百家号博客园抖音小红书 你的文章也可以这样分发 墨衍会员 ¥399起/年,写一次发全网
我也要 关注 + 加入社区
# -*- coding: utf-8 -*-

"""

Created on Fri Aug 11 16:31:42 2017

@author: lart

"""


import urllib.request

import re, time


def req_open_html(url):

    print('req_open_html begin')

    headers = {'User-Agent': 'Mozilla/5.0 (Windows NT 6.3; Win64; x64; rv:55.0) Gecko/20100101 Firefox/55.0'}

    request = urllib.request.Request(url, headers=headers)

    html = urllib.request.urlopen(request).read().decode('GBK')

    print('req_open_html end')

    return html


def re_find_match(re_string, operation, html):

    print('re_find_match begin')

    pattern = re.compile(re_string, re.I)

    if operation == 'findall':

        result = pattern.findall(html)

    elif operation ==  'match':

        result = pattern.match(html)

    else:

        print('this operation is invalid')

        exit(-1)

    print('re_find_match end')

    return result


if __name__ == '__main__':

    url_base = 'http://www.7kankan.la/book/1/'

    html = req_open_html(url_base)

    findall_title = re_find_match(r'<title>(.+?)</title>', 'findall', html)

    findall_article = re_find_match(r'<dd class="col-md-3"><a href=[\',"](.+?)[\',"] title=[\',"](.+?)[\',"]>', 'findall', html)


    with open(findall_title[0] + '.txt', 'w+', encoding='utf-8') as open_file:

        print('article文件打开', findall_article)

        for i in range(len(findall_article)):

            print(i)

            open_file.write(findall_article[i][1] + '\n ---------------------------------------------- \n')

            url_arctile = url_base + findall_article[i][0]

            html_article = req_open_html(url_arctile)

            findall_article_txet = re_find_match(r'    (.+?)<br />', 'findall', html_article)

            findall_article_next = findall_article[i][0].replace('.html', '_2.html')

            url_arctile_next = url_base + findall_article_next

            html_article_next = req_open_html(url_arctile_next)

            if html_article_next:

                findall_article_txet.extend(re_find_match(r'    (.+?)<br />', 'findall', html_article_next))

                for text in findall_article_txet:

                    open_file.write(text + '\n')

            time.sleep(1)


    print('文件写入完毕')
Python: 3.5
IDE: wingide 6.0
Sys: WIN 8.1
问题:
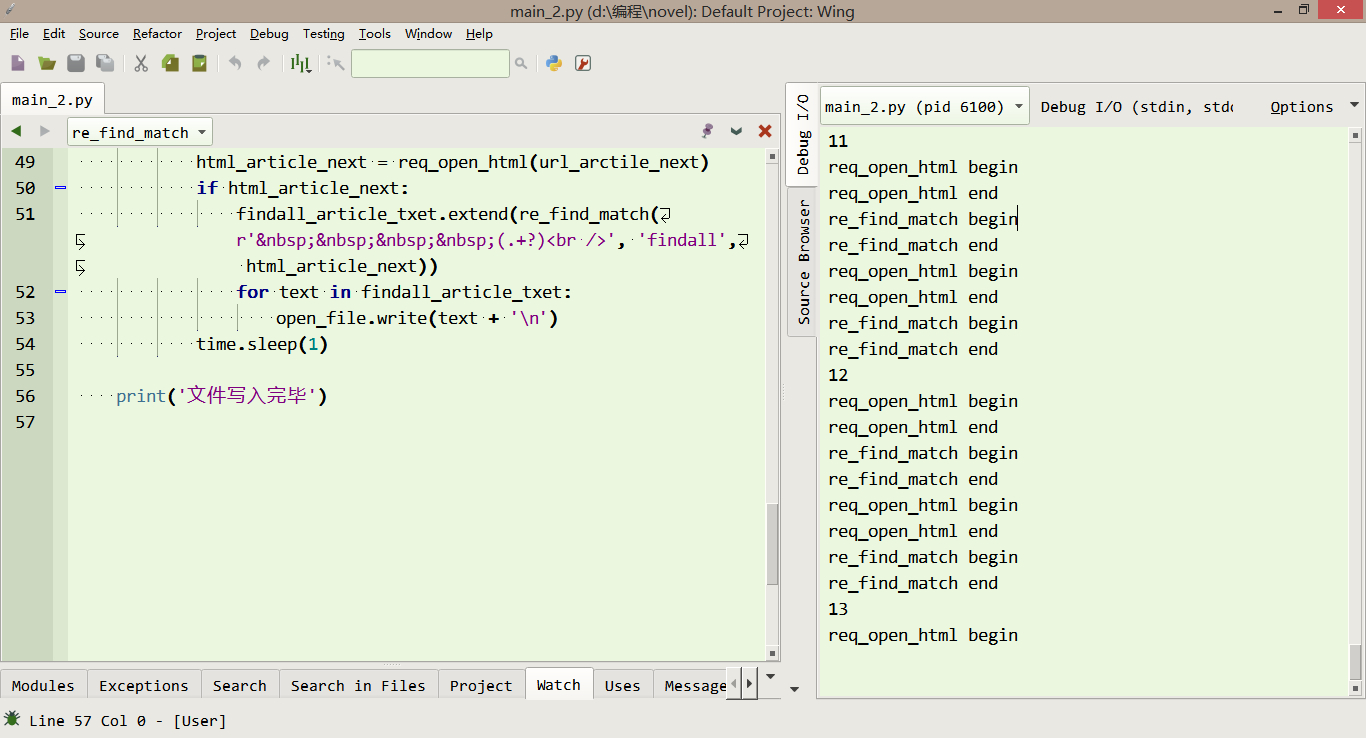
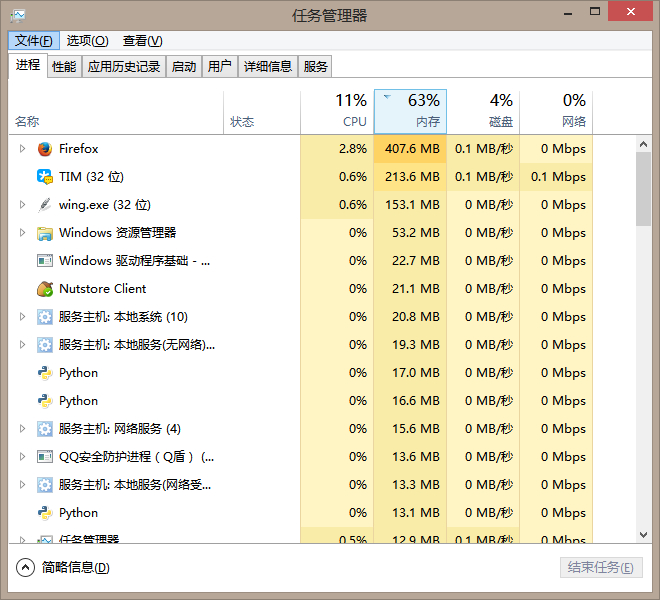
本人电脑运行时,发现,总是会在中途停止输出,也没有报错,只是卡在那里,cpu,内存等等也没有显示出太明显的异常高占用。
我好奇的是,这是因为目标网站的原因,还是我自己代码的问题。下面是任务管理器和IDE的输出截图
...全文
相关推荐
python爬虫项目设置一个中断重连的程序的实现
### Python爬虫项目中断重连程序的实现在进行网络爬虫开发时,经常会遇到一些不可预测的问题,比如网络波动、服务器拒绝响应等,这些问题都可能导致爬虫在中途停止运行。
基于Python的网络爬虫技术研究
基于Python的网络爬虫技术实现#### 2.1 抓取与解析的实现利用Python实现网络爬虫时,可以选择合适的请求方法(如GET或POST)与目标网站进行交互。
大数据环境下基于python的网络爬虫技术.pdf
网络爬虫(又称网页蜘蛛、网络机器人)是一种能够自动地、按照既定规则抓取网页信息的程序或脚本。它按照既定的规则,自动抓取万维网上的数据,是搜索引擎获取内容的重要组成部分。
网络爬虫—python和数据分析
网络爬虫是一种能够自动提取网页内容的程序,它是搜索引擎获取信息的核心技术之一。
网络爬虫Python和数据分析
"网络爬虫Python和数据分析"网络爬虫是一种自动抓取互联网网页的程序,主要用于搜索引擎的数据收集。它们通常从一个或多个起始URL出发,不断抓取页面并提取新的URL,直到达到预设的停止条件。网




