

 脚本语言

请教各位大神爬虫编码问题
 墨衍会员 · AI 创作全网分发 墨衍智能分发 通过墨衍一键同步至各平台 可同步平台 CSDN微信公众号微博知乎掘金百家号博客园抖音小红书 你的文章也可以这样分发 墨衍会员 ¥399起/年,写一次发全网
我也要 关注 + 加入社区
代码如下:
#!/usr/bin/env python
# -*- coding:utf-8 -*-
import urllib,urllib2
import sys
page = 1
url = 'http://www.qiushibaike.com/hot/page/1' + str(page)
user_agent = 'Mozilla/5.0 (Windows NT 10.0; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.106 Safari/537.36'
headers = {
'Accept':'text/html,application/xhtml+xml,application/xml;q=0.9,image/webp,*/*;q=0.8',
'Accept-Encoding':'gzip, deflate, sdch, br',
'Accept-Language':'zh-CN,zh;q=0.8',
'AlexaToolbar-ALX_NS_PH':'AlexaToolbar/alx-4.0',
'Cache-Control':'max-age=0',
'Connection':'keep-alive',
'Cookie':'_xsrf=2|242ca447|bd506c7f8bc26e48eae656ed4c19d099|1510131460',
'Host':'www.qiushibaike.com',
'Upgrade-Insecure-Requests':'1',
'User-Agent':'Mozilla/5.0 (Windows NT 10.0; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.106 Safari/537.36',
}
try:
request = urllib2.Request(url,headers = headers)
reponse = urllib2.urlopen(request)
c = reponse.read()
print c
except urllib2.URLError, e:
if hasattr(e,"code"):
print e.code
if hasattr(e,"reason"):
print e.reason
运行后爬了一堆乱码,改为c = reponse.read().decode('utf-8')后报错,如下:
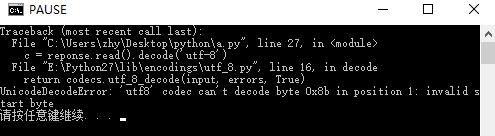
网上找了很多帖子也不知道怎么解决
#!/usr/bin/env python
# -*- coding:utf-8 -*-
import urllib,urllib2
import sys
page = 1
url = 'http://www.qiushibaike.com/hot/page/1' + str(page)
user_agent = 'Mozilla/5.0 (Windows NT 10.0; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.106 Safari/537.36'
headers = {
'Accept':'text/html,application/xhtml+xml,application/xml;q=0.9,image/webp,*/*;q=0.8',
'Accept-Encoding':'gzip, deflate, sdch, br',
'Accept-Language':'zh-CN,zh;q=0.8',
'AlexaToolbar-ALX_NS_PH':'AlexaToolbar/alx-4.0',
'Cache-Control':'max-age=0',
'Connection':'keep-alive',
'Cookie':'_xsrf=2|242ca447|bd506c7f8bc26e48eae656ed4c19d099|1510131460',
'Host':'www.qiushibaike.com',
'Upgrade-Insecure-Requests':'1',
'User-Agent':'Mozilla/5.0 (Windows NT 10.0; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.106 Safari/537.36',
}
try:
request = urllib2.Request(url,headers = headers)
reponse = urllib2.urlopen(request)
c = reponse.read()
print c
except urllib2.URLError, e:
if hasattr(e,"code"):
print e.code
if hasattr(e,"reason"):
print e.reason
运行后爬了一堆乱码,改为c = reponse.read().decode('utf-8')后报错,如下:
网上找了很多帖子也不知道怎么解决
...全文
相关推荐
Python网络爬虫出现乱码问题的解决方法
Python网络爬虫在抓取网页数据时,可能会遇到各种乱码问题,这主要源于源网页的编码和爬虫程序处理编码之间存在不匹配。解决乱码的关键在于正确地识别和处理网页的编码。首先,我们需要了解乱码产生的原因。
java 网络爬虫源码
**异常处理**:处理可能出现的网络错误、编码问题、无效响应等情况,确保程序的稳定性和健壮性。5. **并发与多线程**:对于大规模的网页抓取,可能需要使用多线程或异步处理来提高效率。6.
Python网络爬虫代码
**异常处理**:考虑到网络爬虫可能遇到的各种问题,如超时、重定向、编码错误等,良好的异常处理机制是必要的。使用try-except语句块可以确保程序在遇到问题时不会崩溃。6.
网络爬虫,数据采集源代码
网络爬虫,也被称为网页蜘蛛或网络机器人,是一种自动化程序,用于系统地浏览互联网并抓取所需信息。在IT行业中,网络爬虫是数据采集的关键技术,尤其在大数据分析、市场研究、搜索引擎优化等领域有着广泛的应用。
用c++写的网络爬虫
《C++实现的网络爬虫详解》网络爬虫,又称网络蜘蛛或网络机器人,是一种自动遍历互联网并抓取网页信息的程序。




