183
社区成员
 发帖
 与我相关
 我的任务
 分享
| The Link Your Class | https://bbs.csdn.net/forums/MUEE308FZ |
|---|---|
| The Link of Requirement of This Assignment | https://bbs.csdn.net/topics/603608738 |
| Group number | 5 |
| Group members | 19105592 & 831902115 |
| Group members | 19105932 & 831902104 |
| Group members | 19104031 & 831902114 |
| Group members | 19105576 & 831902202 |
| Group members | 19105576 & 831902202 |
| Prototype link | https://modao.cc/app/2b6d0e10d09d3fb7ef180a36c7b0d17cc1f93e19 |
| Demand specification link | https://www.kdocs.cn/view/l/cmE0OFz6PfES |
P1:The front-end design is different from the expected model
The front-end design is different from the expected model,and some components cannot be displayed in the development software, so we slightly changed the previous model design. While adapting the development software page, we try to be similar to the original model as much as possible.
P2:Interception of user login information
We can grab user information, but it cannot be displayed in the back-end program, causing the user to be unable to log in to the account.
We find the getStoragesync function to solve the problem, help the user to obtain information, and change the test number to the development number.
P3:The complement of crawler
Get the initial URL. The initial URL address can be manually specified by the user, or it can be determined by one or several initial crawling webpages specified by the user.
Crawl the page according to the initial URL and obtain a new URL. After obtaining the initial URL address, you first need to crawl the corresponding
The web page in the URL address, after crawling the web page in the corresponding URL address, the web page is stored in the original database, and while crawling the web page, the new URL address is found, and the crawled URL address is stored in A URL list is used to remove duplicates and determine the crawling process.
Put the new URL in the URL queue. In step 2, after obtaining the next new UR address, the new URL address will be placed in the URL queue.
Read the new URL from the URL queue, crawl the web page according to the new URL, obtain the new URL from the new web page at the same time, and repeat the above-mentioned crawling process.
When the stop conditions set by the crawler system are met, the crawling stops. When writing a crawler, the corresponding stop conditions are generally set. If the stop condition is not set, the crawler will continue to crawl until it cannot obtain a new URL address. If the stop condition is set, the crawler will stop crawling when the stop condition is met.
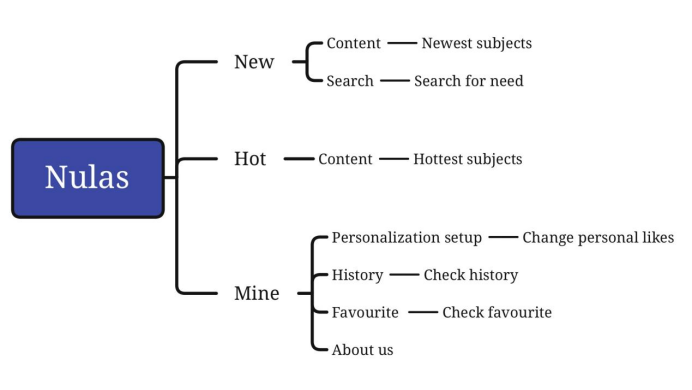
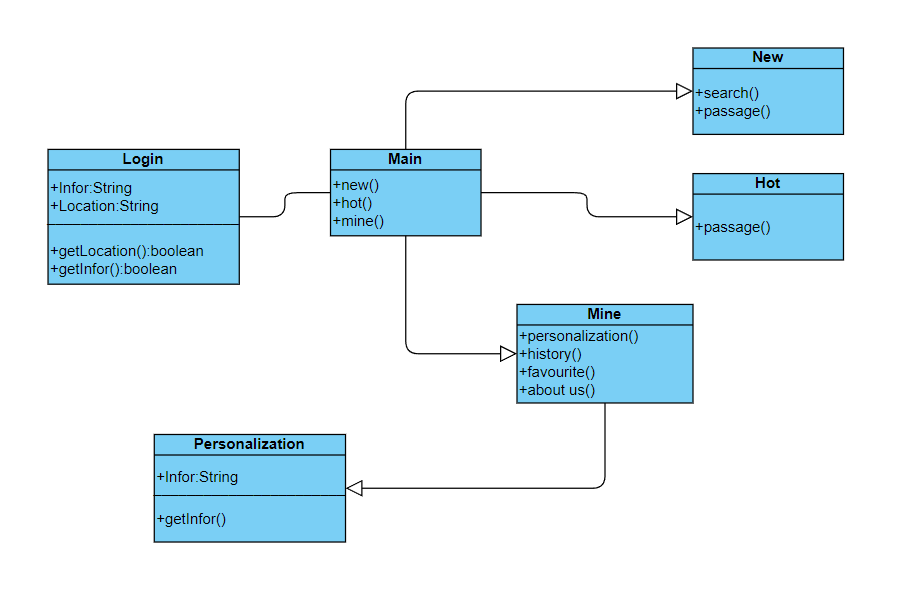
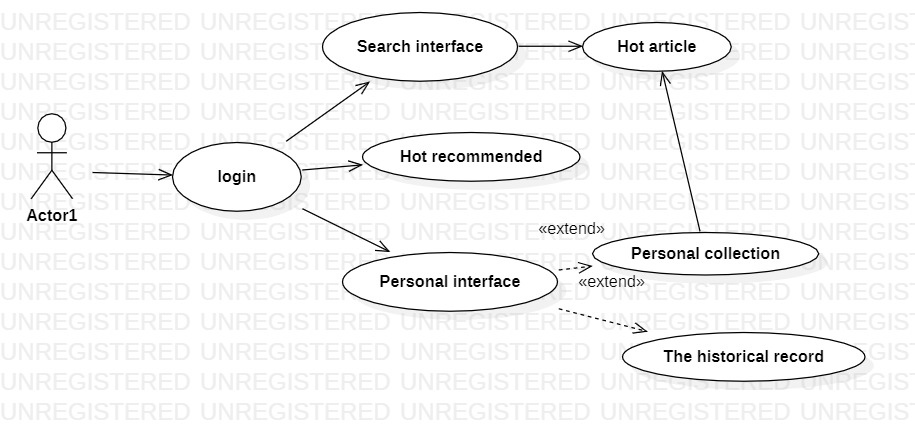
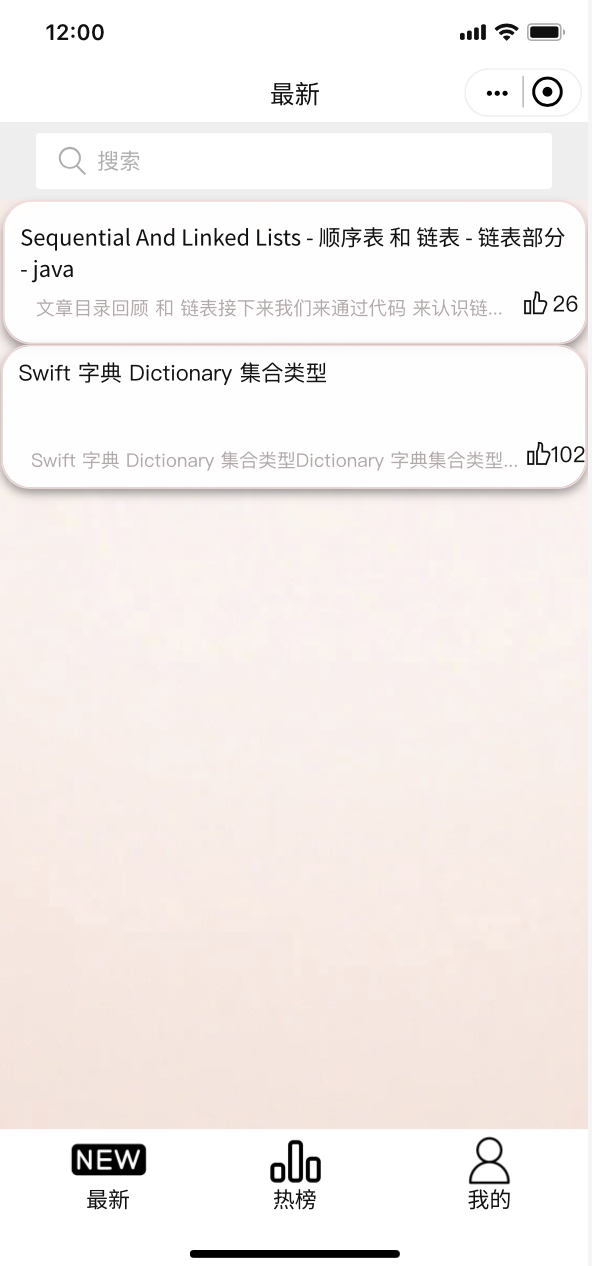
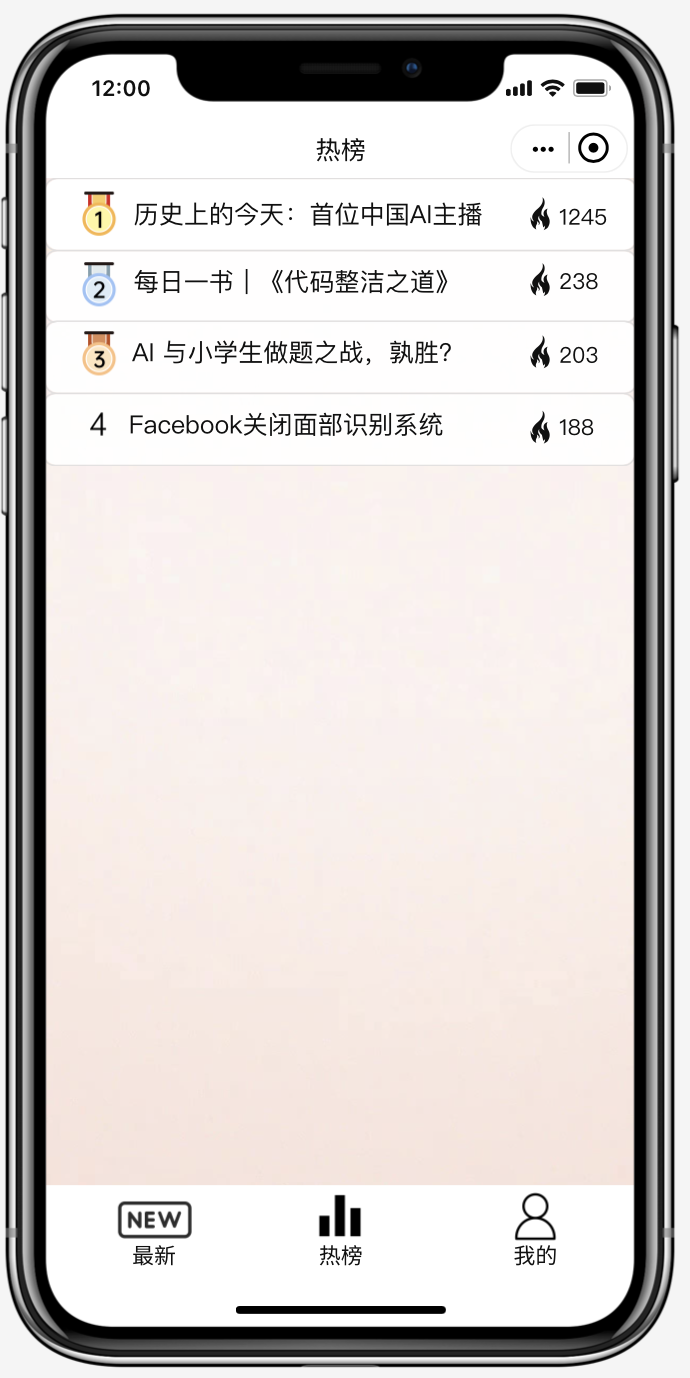
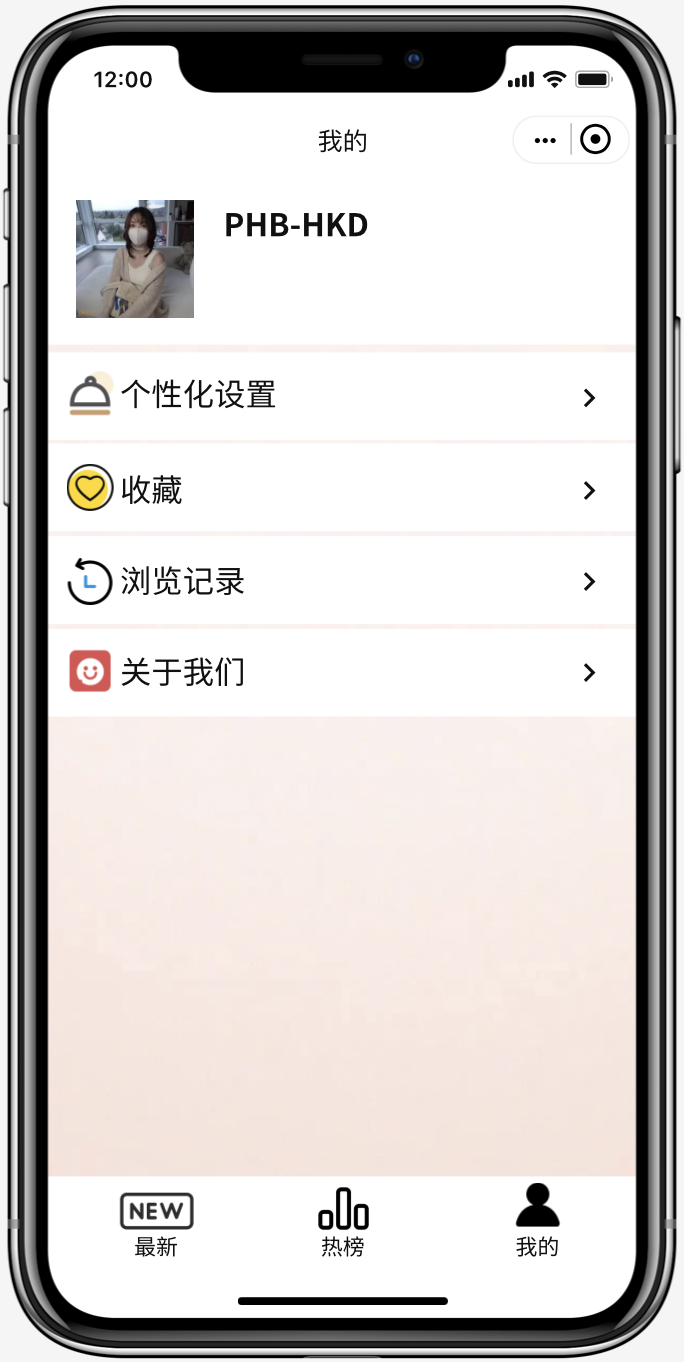
Our design concept is in the home page, we configured with a search box, by keyword lookup the knowledge we can search for hot spots and articles, in the search box below we set the articles read interface, we can point into the into the hot topic of the reading, at the same time through our background for information gathering on the hot spots, and through the heat of the hot knowledge, We will conduct a heat sorting, we will in recent popular network knowledge, and some popular virtual network news show, such as hot recently do is yuan of the universe, in the list we will according to the heat to the arrangement of the order, it is more advantageous to the user for information analysis and find their own pay more attention to the information of hot, We also have a user interface, you can view your collection and some personal information, but also set some of their own labels, to show their range of interest, we can according to these labels, to recommend more suitable for your information, as well as some programming learning methods.
Leader Yue Zhuo :
After this laboratory, I deeply realized the importance of rational distribution of work content and teamwork. In this process, all five of us encountered different problems, but with our timely communication, we effectively solved each difficulty.
Teammate 1 Yanqi Fan :
In this experiment, since our small program needs the support of back-end code, I worked hard to learn the knowledge related to pathon crawler in my spare time and made progress in exploration, which greatly strengthened my learning and application ability.
Teammate 2 Chuan He :
After seven days of hard work, I think this is a great breakthrough for myself. Before that, my ability in art can be said to be very poor, but because of this, my team leader arranged the front-end design for me. Through the design of the front-end user interface of the applet, I exercised my art and typesetting ability to a great extent, I am very grateful to the captain for his wise arrangement.
Teammate 3 Yaxing Li :
During the cooperation with my teammates, I learned how to realize the data interaction between the front end and the back end. , Meanwhile ,my teamwork ability has also been improved. I also improved my coding ability in the process. It was a wonderful experience!
Teammate 4 Jinhan Lin :
In the past seven days, I've learned a lot of useful back-end knowledge and learned a variety of programming languages to laid a good foundation of our laboratory . In this process, my teammates and I cooperated with each other, developed and applied the knowledge we had mastered in practices,which not only exercises my teamwork ability, but also improves my cognition and understanding of the team.