

 新疆政法学院

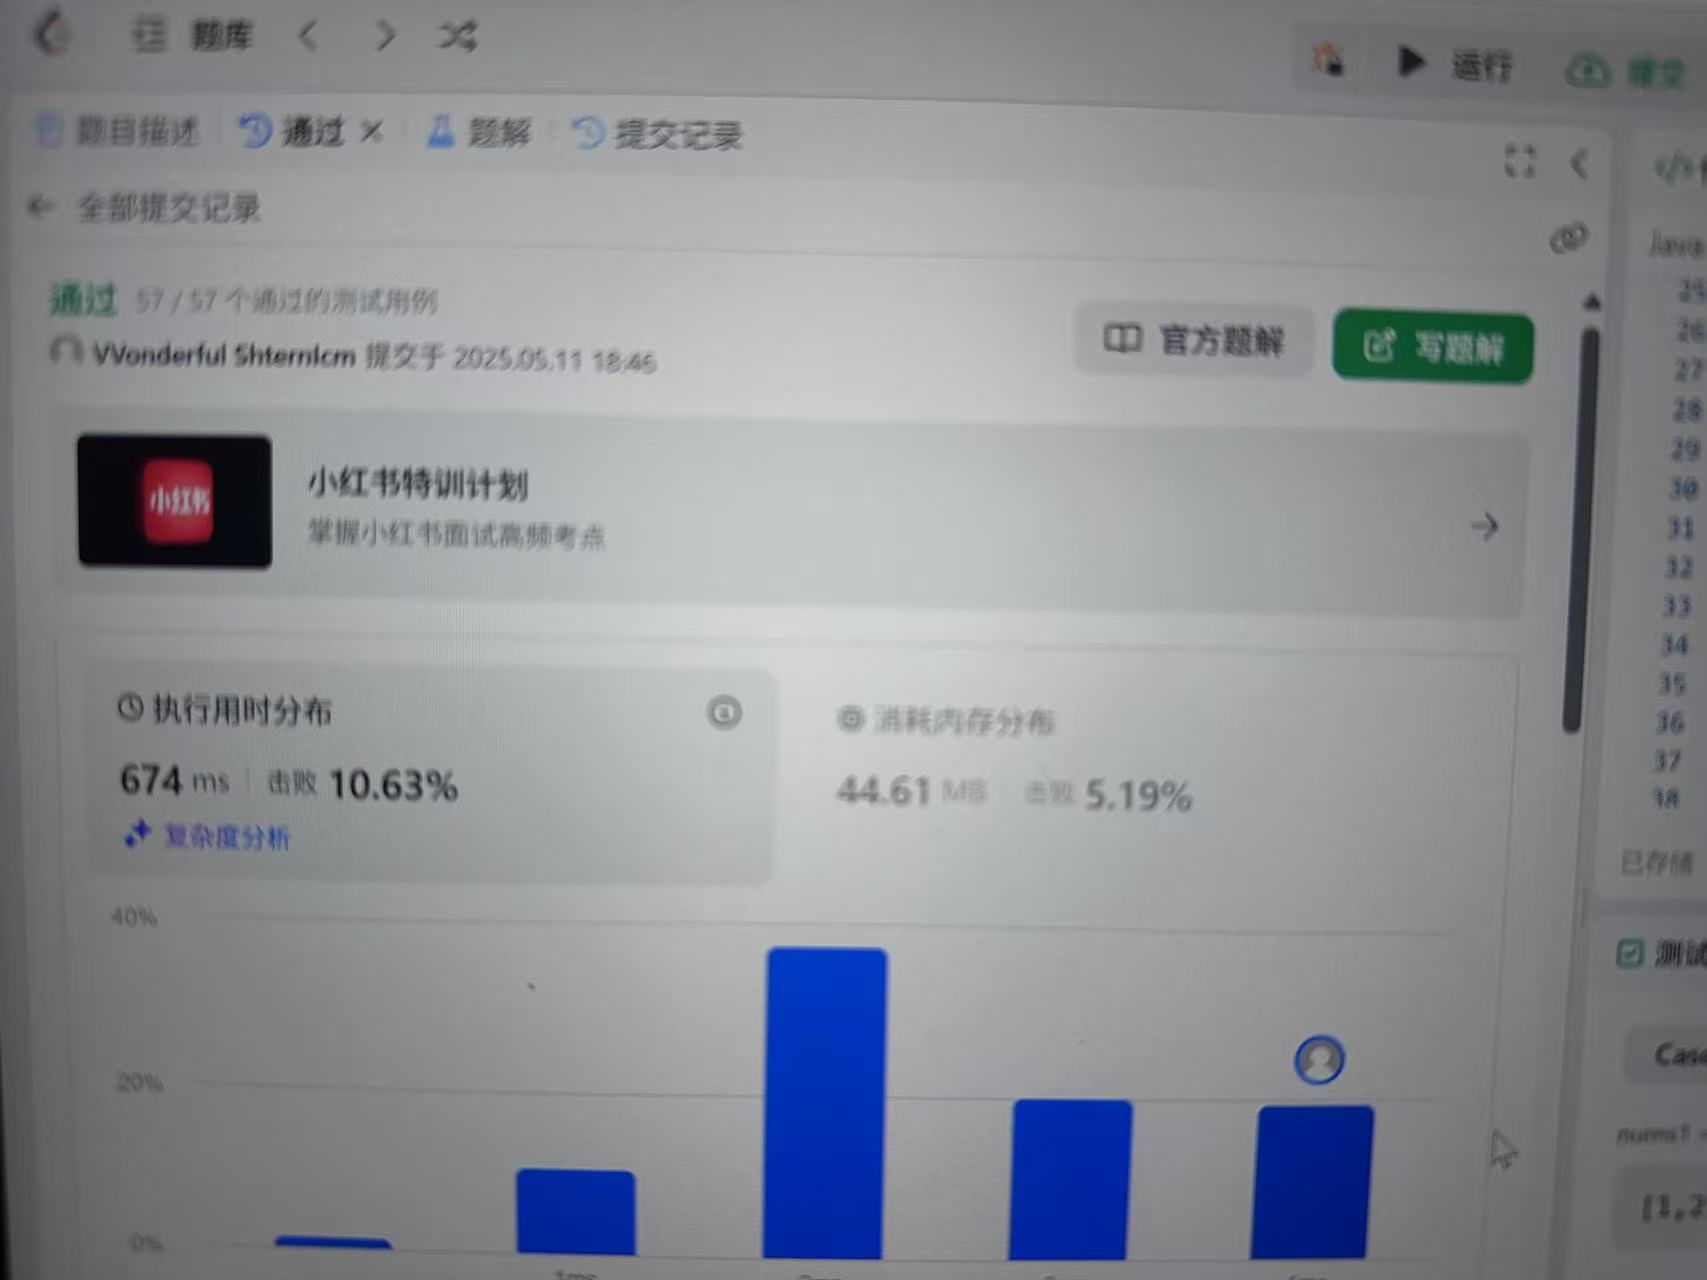
两个数组的交集,超低效率栈法。。。
 墨衍会员 · AI 创作全网分发 墨衍智能分发 通过墨衍一键同步至各平台 可同步平台 CSDN微信公众号微博知乎掘金百家号博客园抖音小红书 你的文章也可以这样分发 墨衍会员 ¥399起/年,写一次发全网
我也要 关注 + 加入社区
豆包AI支持
import java.util.*;

public int[] intersection(int[] nums1, int[] nums2) {
    // 1. 将数组转换为栈(栈顶为数组最后一个元素)
    Stack<Integer> stack1 = arrayToStack(nums1);
    Stack<Integer> stack2 = arrayToStack(nums2);

    // 2. 创建临时栈用于存储共同元素
    Stack<Integer> commonStack = new Stack<>();

    // 3. 复制stack1到temp1(避免修改原栈)
    Stack<Integer> temp1 = new Stack<>();
    temp1.addAll(stack1);

    // 4. 遍历stack2(元素顺序与原数组相反)
    Stack<Integer> temp2 = new Stack<>();
    while (!stack2.isEmpty()) {
        int num = stack2.pop(); // 弹出stack2的栈顶元素

        // 5. 检查temp1中是否存在该元素(时间复杂度O(n))
        if (contains(temp1, num)) {
            commonStack.push(num); // 存在则加入共同元素栈
        }

        // 6. 使用temp2保存stack2的弹出元素,以便后续恢复
        temp2.push(num);
    }

    // 7. 恢复stack2的原始顺序(元素顺序与原数组相反)
    while (!temp2.isEmpty()) {
        stack2.push(temp2.pop());
    }

    // 8. 将共同元素栈转换为Set去重,并转为数组返回
    Set<Integer> uniqueCommon = new HashSet<>(commonStack);
    int[] result = new int[uniqueCommon.size()];
    int index = 0;
    for (int num : uniqueCommon) {
        result[index++] = num;
    }

    return result;
}

private Stack<Integer> arrayToStack(int[] arr) {
    Stack<Integer> stack = new Stack<>();
    for (int num : arr) {
        stack.push(num); // 按数组顺序压栈,栈顶为数组最后一个元素
    }
    return stack;
}
private boolean contains(Stack<Integer> stack, int target) {
    Stack<Integer> temp = new Stack<>();
    boolean found = false;

    // 1. 遍历栈查找元素(时间复杂度O(n))
    while (!stack.isEmpty()) {
        int num = stack.pop();
        if (num == target) {
            found = true;
        }
        temp.push(num); // 保存元素到临时栈
    }

    // 2. 恢复原栈的顺序(元素顺序不变)
    while (!temp.isEmpty()) {
        stack.push(temp.pop());
    }

    return found;
}
举个例子(豆包举例
数组转换为栈:
对于 nums1,调用 arrayToStack(nums1) 后,stack1 为 [1, 2, 3](栈顶为 3)。
对于 nums2,调用 arrayToStack(nums2) 后,stack2 为 [2, 3, 4](栈顶为 4)。
创建临时栈和复制操作:
创建 commonStack 用于存储共同元素,初始为空栈。
复制 stack1 到 temp1,temp1 为 [1, 2, 3](栈顶为 3)。
遍历 stack2 并检查元素:
开始遍历 stack2,stack2 栈顶元素 num = 4,调用 contains(temp1, 4):
contains 方法中,temp 初始为空栈,found 为 false。
遍历 temp1,temp1 栈顶元素为 3,不等于 4,将 3 压入 temp,继续遍历。
temp1 栈顶元素为 2,不等于 4,将 2 压入 temp,继续遍历。
temp1 栈顶元素为 1,不等于 4,将 1 压入 temp,遍历结束,found 仍为 false,contains 方法返回 false,commonStack 不变。
将 4 压入 temp2。
stack2 栈顶元素 num = 3,调用 contains(temp1, 3):
contains 方法中,temp 初始为 [1, 2, 3](temp1 恢复后的状态),found 为 false。
遍历 temp1,temp1 栈顶元素为 3,等于 3,found 变为 true,将 3 压入 commonStack,contains 方法返回 true。
将 3 压入 temp2。
stack2 栈顶元素 num = 2,调用 contains(temp1, 2):
contains 方法中,temp 初始为 [1, 2](temp1 恢复后的状态),found 为 false。
遍历 temp1,temp1 栈顶元素为 2,等于 2,found 变为 true,将 2 压入 commonStack,contains 方法返回 true。
将 2 压入 temp2。
stack2 为空,遍历结束。
恢复 stack2 的原始顺序:
从 temp2 中依次弹出元素并压入 stack2,stack2 恢复为 [2, 3, 4]。
转换结果:
将 commonStack 转换为 HashSet 去重,uniqueCommon 为 [2, 3]。
创建 result 数组,将 uniqueCommon 中的元素放入 result 数组,result 为 [2, 3]。
相关推荐
低效率原因分析.doc
- 超用工时:实际花费的时间超过准工时,表明效率低于预期,可能是流程问题、员工技能不足或设备故障等导致的。 - 单位效率:以每个单位产品计算的效率,便于比较不同产品或批次的生产效率。3.
简化STL接口:为QF应用创造更友好的界面
本文探讨了如何通过封装STL中的set<T>和map<K,V>容器,以创建更适用于金融工程(QF)应用的用户友好类。文章首先介绍了集合和映射的基本概念,随后展示了如何在QF应用程序中应用这些数据结构,并通过示例代码展示了它们的使用方法。此外,文章还讨论了如何通过封装和接口简化来提高STL容器在特定应用中的可用性,并提供了与金融建模相关的实际应用案例。
低效率原因分析格式.doc
文档标题“低效率原因分析格式.doc”和描述表明,这是一个用于分析工作效率低下问题的管理工具。这个工具可能是一个表格,用于记录和分析生产过程中的效率数据,以找出导致低效率的原因。
低效率原因分析(表格模板、DOC格式).doc
**准工时**和**超用工时**:准工时是预计完成特定任务所需的时间,而超用工时则是实际超过的工时。两者的差距可以揭示生产过程中的延迟和效率损失。7.
浅析证券市场低效率制度.doc
【证券市场低效率的成因】证券市场的低效率通常源于多个因素。政策干预可能导致市场价格失真,如政府对特定行业的扶持或限制措施。市场操纵行为,如内幕交易或庄家操盘,会扭曲价格信号。




